Filter by type:
Filter by tags:

hy4-preview
# Hy4-preview GGUF
Three GGUF builds of Hy4-Preview: https://huggingface.co/tencent/Hy4-preview
**Language / 语言:** English · 中文
**Neither file runs on stock llama.cpp.** The `hyv4` architecture is not upstream. Apply the
patches in `hy4-preview-patch/`
## English
### 1. What these are
**`Hy4-preview-Q4_K_M.gguf`** — a conventional Q4_K_M. Most tensors are Q4_K; `ffn_down_exps`
gets Q6_K on 37 layers via llama.cpp's own logic. Use this unless you are memory-constrained.
**`Hy4-preview-UD-IQ1_M.gguf`** - mixed precision with UD-IQ1_M strategy at ~2.44 bpw, roughly **half the size** for the
same model. The routed-expert `gate`/`up` projections run at 1.75 bpw (IQ1_M) and 2.0625 bpw (IQ2_XXS).
**`Hy4-preview-STQ1_0.gguf`** — mixed precision with MIX-STQ1_0 strategy at ~2.38 bpw, roughly **half the size** for the
same model. The routed-expert `gate`/`up` projections run at 1.3125 bpw (STQ1_0) on 29 layers and
2.0625 bpw (IQ2_XXS) on the other 48. See section 3.
### 2. Running them
Build a patched llama.cpp
```bash
git clone https://github.com/ggml-org/llama.cpp && cd llama.cpp
git checkout 0cea36222
...
Repository: localai

deepseek-v4-flash-0731
# DeepSeek-V4-Flash-0731
Technical Report👁️
## Introduction
**DeepSeek-V4-Flash-0731** is the official release of **DeepSeek-V4-Flash**, superseding the preview version, with substantially enhanced agentic capabilities. It has the same model structure as DeepSeek-V4-Flash-DSpark, i.e. it comes with a speculative decoding module attached.
DeepSeek-V4-Flash-0731 outperforms DeepSeek-V4-Pro (Preview) on benchmarks listed below despite its far smaller activated parameter count, and is broadly competitive with the strongest proprietary models available.
Notes:
1. For the Code Agent tasks among the public benchmarks above, DeepSeek-V4-Flash-0731 is evaluated with the minimal mode of DeepSeek Harness (to be released) as the agent framework, using the `max` reasoning effort level with `temperature = 1.0, top_p = 0.95`.
2. † DSBench-FullStack is an internal full-stack development test set; DSBench-Hard is an internal test set of difficult coding-agent problems.
## Chat Template
...
Repository: localaiLicense: mit
deepseek-v4-flash
# DeepSeek-V4: Towards Highly Efficient Million-Token Context Intelligence
Technical Report👁️
## Introduction
We present a preview version of **DeepSeek-V4** series, including two strong Mixture-of-Experts (MoE) language models — **DeepSeek-V4-Pro** with 1.6T parameters (49B activated) and **DeepSeek-V4-Flash** with 284B parameters (13B activated) — both supporting a context length of **one million tokens**.
DeepSeek-V4 series incorporate several key upgrades in architecture and optimization:
1. **Hybrid Attention Architecture:** We design a hybrid attention mechanism combining Compressed Sparse Attention (CSA) and Heavily Compressed Attention (HCA) to dramatically improve long-context efficiency. In the 1M-token context setting, DeepSeek-V4-Pro requires only **27% of single-token inference FLOPs** and **10% of KV cache** compared with DeepSeek-V3.2.
2. **Manifold-Constrained Hyper-Connections (mHC):** We incorporate mHC to strengthen conventional residual connections, enhancing stability of signal propagation across layers while preserving model expressivity.
3. **Muon Optimizer:** We employ the Muon optimizer for faster convergence and greater training stability.
...
Repository: localaiLicense: mit
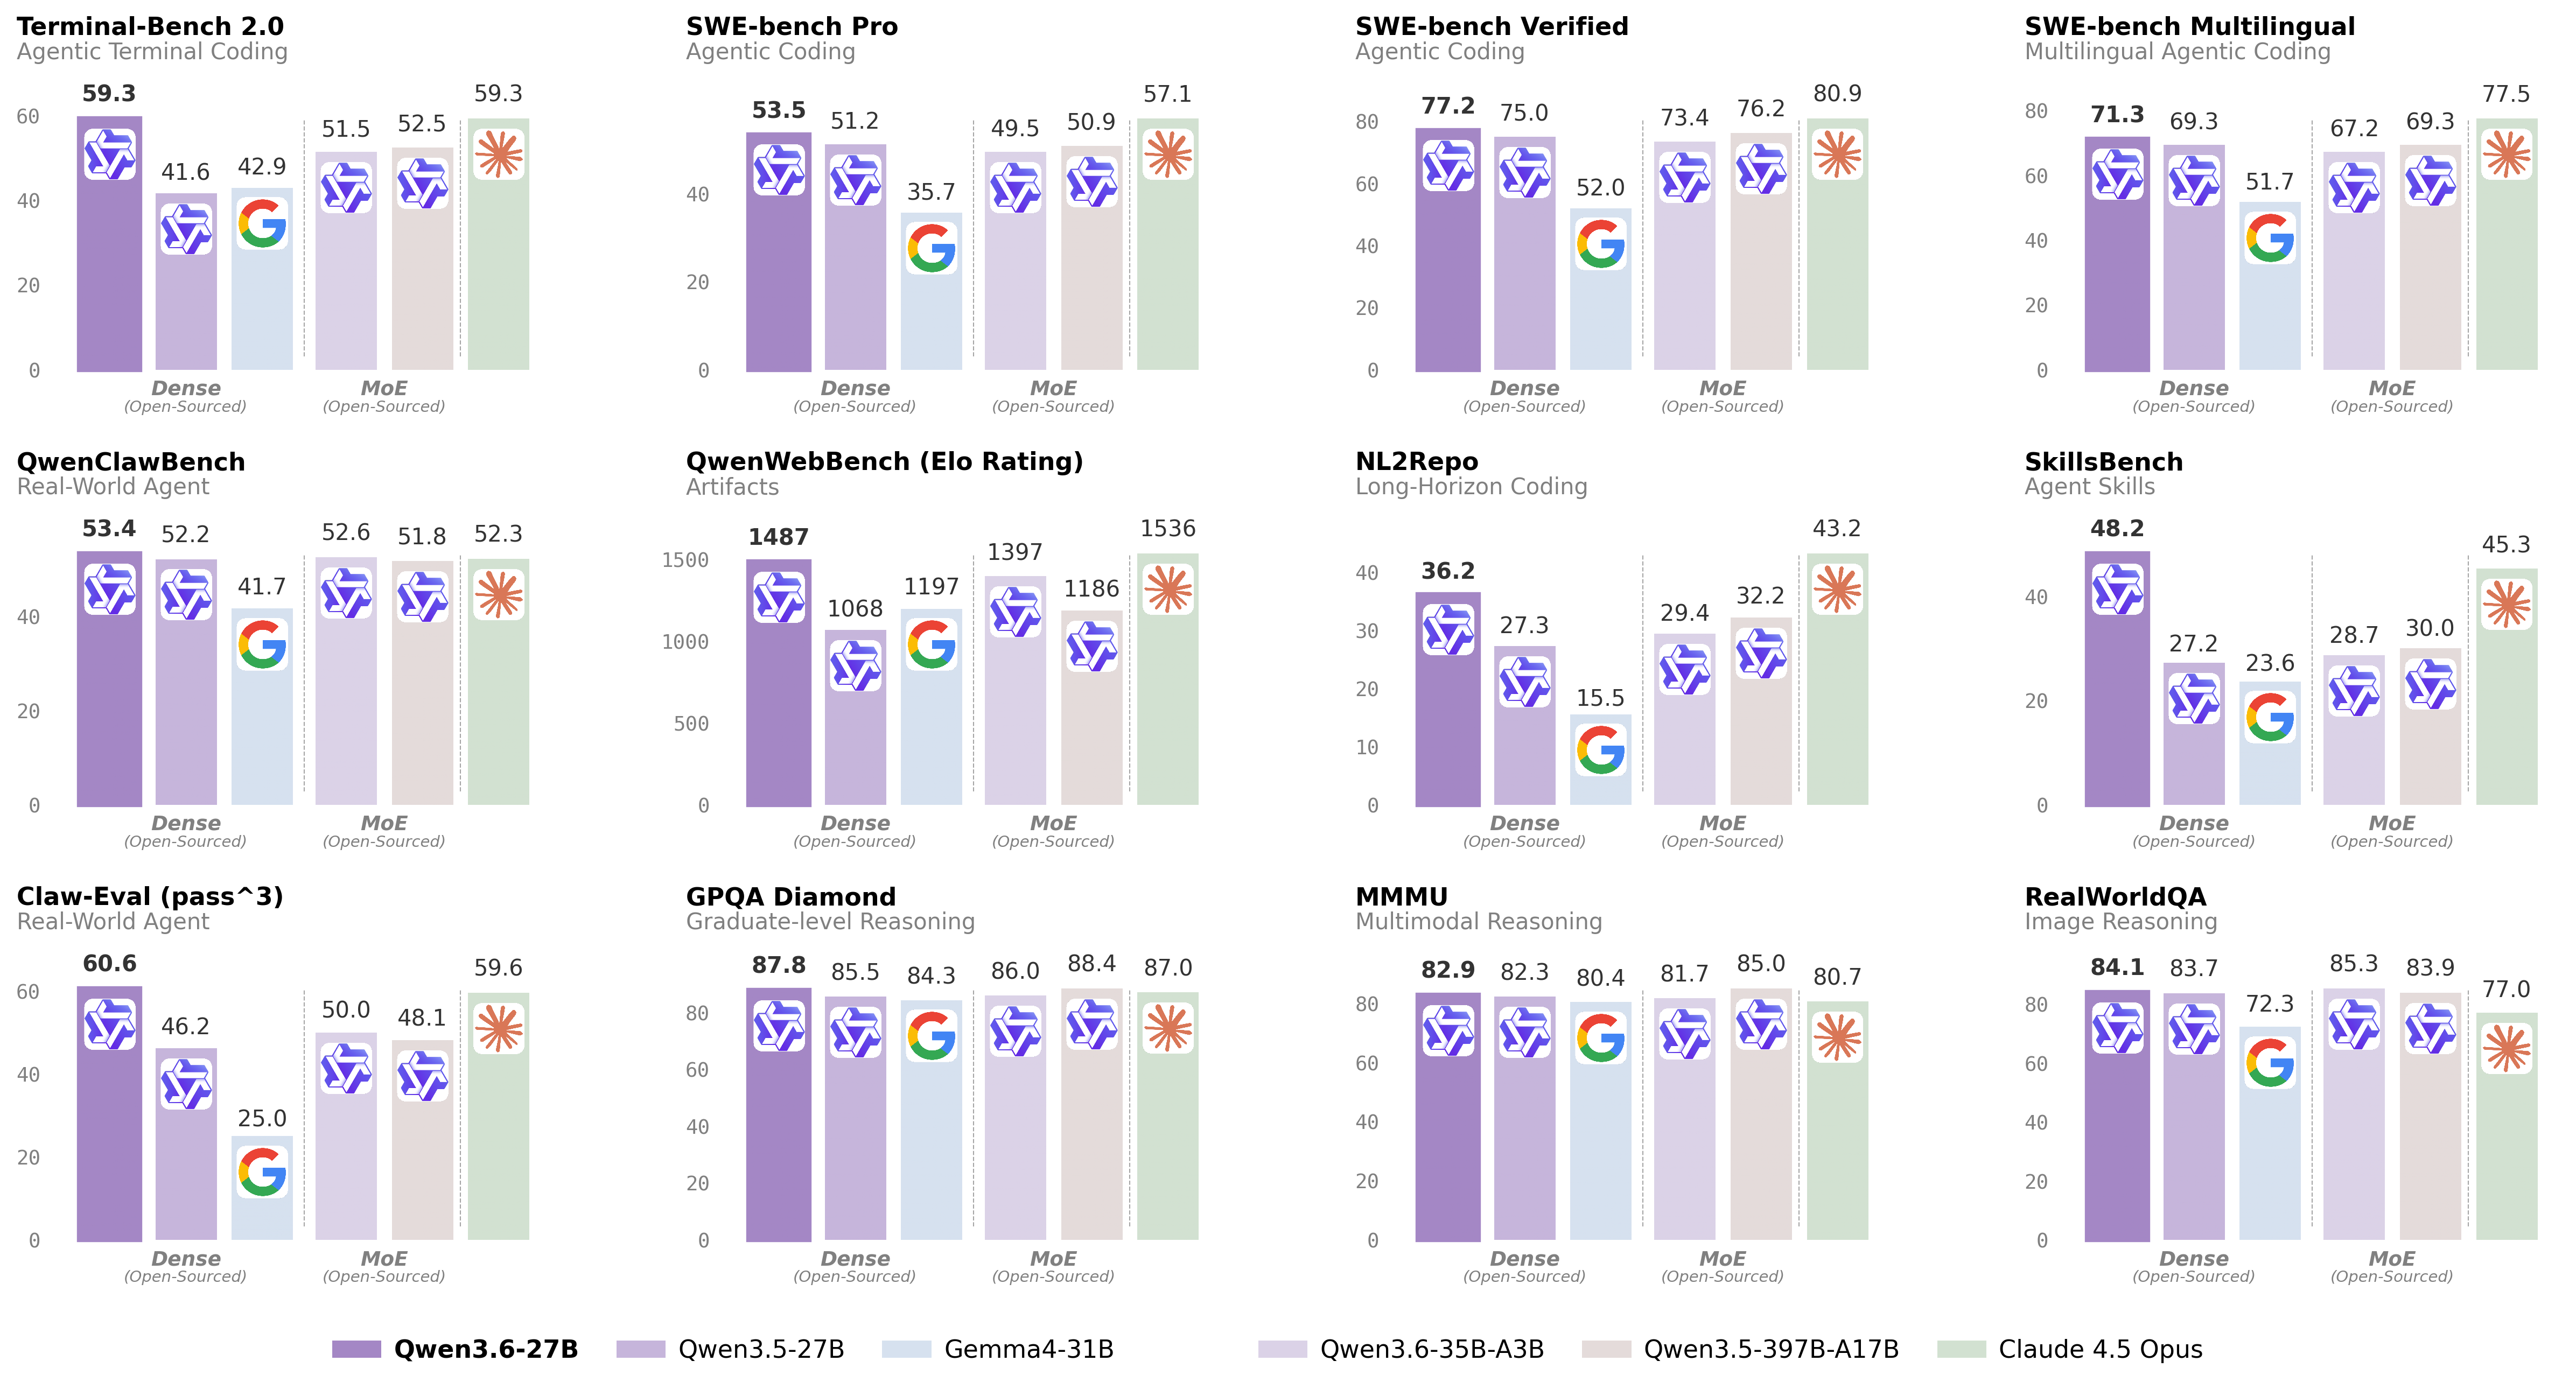
qwopus3.6-27b-v1-preview
# Qwen3.6-27B
[](https://chat.qwen.ai)
> [!Note]
> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
>
> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, KTransformers, etc.
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
## Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
- **Agentic Coding:** the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
- **Thinking Preservation:** we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
For more details, please refer to our blog post Qwen3.6-27B.
## Model Overview
...
Repository: localaiLicense: apache-2.0
maple-preview-tq1-0-head-q4-k
Maple-Preview is DeepGrove's 20B mixture-of-experts reasoning model
with about 1B active parameters. This build uses TQ1_0
ternary GGUF weights with a Q4_K output head.
It uses the publisher's CPU configuration and embedded Jinja chat
template with an 8K default context. The native context is 128K tokens.
Repository: localaiLicense: mit
maple-preview-tq1-0-head-f16
Maple-Preview is DeepGrove's 20B mixture-of-experts reasoning model
with about 1B active parameters. This build uses TQ1_0
ternary GGUF weights with a F16 output head.
It uses the publisher's CPU configuration and embedded Jinja chat
template with an 8K default context. The native context is 128K tokens.
Repository: localaiLicense: mit
maple-preview-tq2-0-head-q4-k
Maple-Preview is DeepGrove's 20B mixture-of-experts reasoning model
with about 1B active parameters. This build uses TQ2_0
ternary GGUF weights with a Q4_K output head.
It uses the publisher's CPU configuration and embedded Jinja chat
template with an 8K default context. The native context is 128K tokens.
Repository: localaiLicense: mit
maple-preview-tq2-0-head-f16
Maple-Preview is DeepGrove's 20B mixture-of-experts reasoning model
with about 1B active parameters. This build uses TQ2_0
ternary GGUF weights with a F16 output head.
It uses the publisher's CPU configuration and embedded Jinja chat
template with an 8K default context. The native context is 128K tokens.
Repository: localaiLicense: mit

kwaipilot_kwaicoder-autothink-preview
KwaiCoder-AutoThink-preview is the first public AutoThink LLM released by the Kwaipilot team at Kuaishou.
The model merges thinking and non‑thinking abilities into a single checkpoint and dynamically adjusts its reasoning depth based on the input’s difficulty.
Repository: localaiLicense: kwaipilot-license
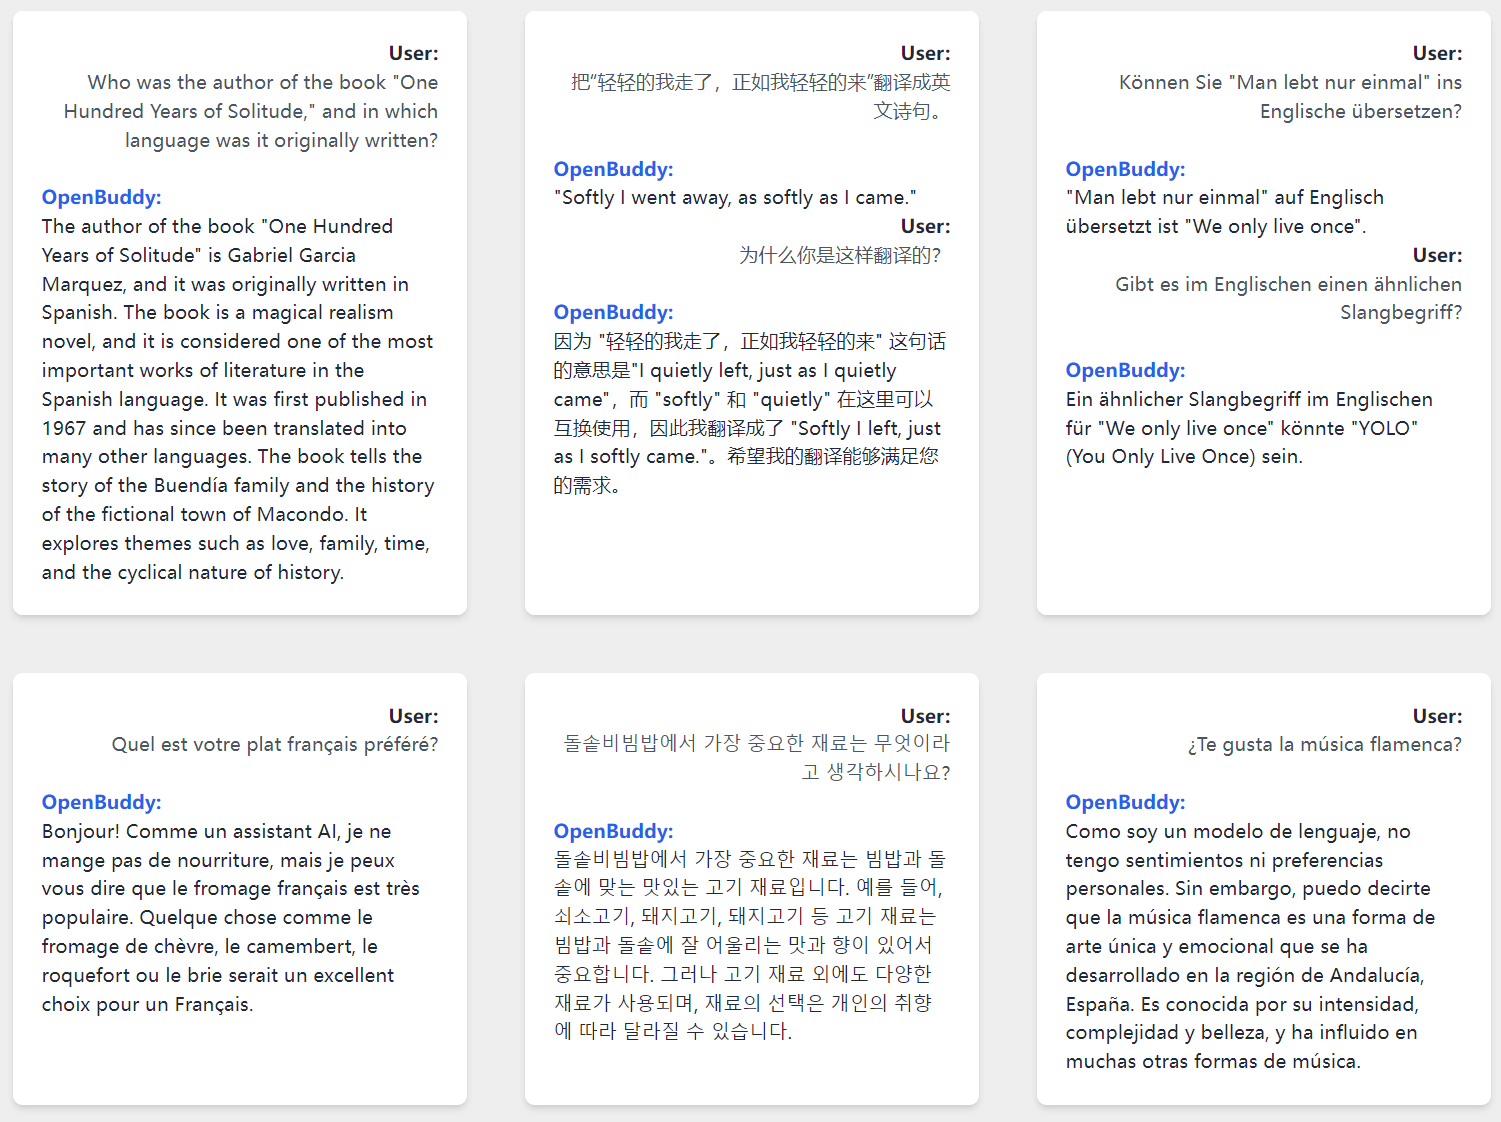
openbuddy_openbuddy-r1-0528-distill-qwen3-32b-preview0-qat
OpenBuddy distillation of Qwen3-32B from DeepSeek-R1, featuring 40K context window and multilingual support (zh, en, fr, de, ja, ko, it, fi). GGUF quantized version optimized for local inference with llama.cpp.
Repository: localaiLicense: apache-2.0
helpingai_dhanishtha-2.0-preview
What makes Dhanishtha-2.0 special? Imagine an AI that doesn't just answer your questions instantly, but actually thinks through problems step-by-step, shows its work, and can even change its mind when it realizes a better approach. That's Dhanishtha-2.0.
Quick Summary:
🚀 For Everyone: An AI that shows its thinking process and can reconsider its reasoning
👩💻 For Developers: First model with intermediate thinking capabilities, 39+ language support
Dhanishtha-2.0 is a state-of-the-art (SOTA) model developed by HelpingAI, representing the world's first model to feature Intermediate Thinking capabilities. Unlike traditional models that provide single-pass responses, Dhanishtha-2.0 employs a revolutionary multi-phase thinking process that allows the model to think, reconsider, and refine its reasoning multiple times throughout a single response.
Repository: localaiLicense: apache-2.0

agentica-org_deepswe-preview
DeepSWE-Preview is a fully open-sourced, state-of-the-art coding agent trained with only reinforcement learning (RL) to excel at software engineering (SWE) tasks. DeepSWE-Preview demonstrates strong reasoning capabilities in navigating complex codebases and viewing/editing multiple files, and it serves as a foundational model for future coding agents. The model achieves an impressive 59.0% on SWE-Bench-Verified, which is currently #1 in the open-weights category.
DeepSWE-Preview is trained on top of Qwen3-32B with thinking mode enabled. With just 200 steps of RL training, SWE-Bench-Verified score increases by ~20%.
Repository: localaiLicense: mit

deepcogito_cogito-v1-preview-llama-70b
The Cogito LLMs are instruction tuned generative models (text in/text out). All models are released under an open license for commercial use.
Cogito models are hybrid reasoning models. Each model can answer directly (standard LLM), or self-reflect before answering (like reasoning models).
The LLMs are trained using Iterated Distillation and Amplification (IDA) - an scalable and efficient alignment strategy for superintelligence using iterative self-improvement.
The models have been optimized for coding, STEM, instruction following and general helpfulness, and have significantly higher multilingual, coding and tool calling capabilities than size equivalent counterparts.
In both standard and reasoning modes, Cogito v1-preview models outperform their size equivalent counterparts on common industry benchmarks.
Each model is trained in over 30 languages and supports a context length of 128k.
Repository: localaiLicense: llama3.1

sophosympatheia_strawberrylemonade-l3-70b-v1.0
This 70B parameter model is a merge of zerofata/L3.3-GeneticLemonade-Final-v2-70B and zerofata/L3.3-GeneticLemonade-Unleashed-v3-70B, which are two excellent models for roleplaying. In my opinion, this merge achieves slightly better stability and expressiveness, combining the strengths of the two models with the solid foundation provided by deepcogito/cogito-v1-preview-llama-70B.
This model is uncensored. You are responsible for whatever you do with it.
This model was designed for roleplaying and storytelling and I think it does well at both. It may also perform well at other tasks but I have not tested its performance in other areas.
Repository: localaiLicense: llama3

nousresearch_deephermes-3-llama-3-3b-preview
DeepHermes 3 Preview is the latest version of our flagship Hermes series of LLMs by Nous Research, and one of the first models in the world to unify Reasoning (long chains of thought that improve answer accuracy) and normal LLM response modes into one model. We have also improved LLM annotation, judgement, and function calling.
DeepHermes 3 Preview is a hybrid reasoning model, and one of the first LLM models to unify both "intuitive", traditional mode responses and long chain of thought reasoning responses into a single model, toggled by a system prompt.
Hermes 3, the predecessor of DeepHermes 3, is a generalist language model with many improvements over Hermes 2, including advanced agentic capabilities, much better roleplaying, reasoning, multi-turn conversation, long context coherence, and improvements across the board.
The ethos of the Hermes series of models is focused on aligning LLMs to the user, with powerful steering capabilities and control given to the end user.
This is a preview Hermes with early reasoning capabilities, distilled from R1 across a variety of tasks that benefit from reasoning and objectivity. Some quirks may be discovered! Please let us know any interesting findings or issues you discover!
Repository: localaiLicense: llama3

deepcogito_cogito-v1-preview-llama-3b
The Cogito LLMs are instruction tuned generative models (text in/text out). All models are released under an open license for commercial use.
Cogito models are hybrid reasoning models. Each model can answer directly (standard LLM), or self-reflect before answering (like reasoning models).
The LLMs are trained using Iterated Distillation and Amplification (IDA) - an scalable and efficient alignment strategy for superintelligence using iterative self-improvement.
The models have been optimized for coding, STEM, instruction following and general helpfulness, and have significantly higher multilingual, coding and tool calling capabilities than size equivalent counterparts.
In both standard and reasoning modes, Cogito v1-preview models outperform their size equivalent counterparts on common industry benchmarks.
Each model is trained in over 30 languages and supports a context length of 128k.
Repository: localaiLicense: llama3.2
llama-3.1-whiterabbitneo-2-8b
WhiteRabbitNeo is a model series that can be used for offensive and defensive cybersecurity.
Models are now getting released as a public preview of its capabilities, and also to assess the societal impact of such an AI.
Repository: localaiLicense: llama3.1

nousresearch_deephermes-3-llama-3-8b-preview
DeepHermes 3 Preview is the latest version of our flagship Hermes series of LLMs by Nous Research, and one of the first models in the world to unify Reasoning (long chains of thought that improve answer accuracy) and normal LLM response modes into one model. We have also improved LLM annotation, judgement, and function calling.
DeepHermes 3 Preview is one of the first LLM models to unify both "intuitive", traditional mode responses and long chain of thought reasoning responses into a single model, toggled by a system prompt.
Hermes 3, the predecessor of DeepHermes 3, is a generalist language model with many improvements over Hermes 2, including advanced agentic capabilities, much better roleplaying, reasoning, multi-turn conversation, long context coherence, and improvements across the board.
The ethos of the Hermes series of models is focused on aligning LLMs to the user, with powerful steering capabilities and control given to the end user.
This is a preview Hermes with early reasoning capabilities, distilled from R1 across a variety of tasks that benefit from reasoning and objectivity. Some quirks may be discovered! Please let us know any interesting findings or issues you discover!
Repository: localaiLicense: llama3

deepcogito_cogito-v1-preview-llama-8b
The Cogito LLMs are instruction tuned generative models (text in/text out). All models are released under an open license for commercial use.
Cogito models are hybrid reasoning models. Each model can answer directly (standard LLM), or self-reflect before answering (like reasoning models).
The LLMs are trained using Iterated Distillation and Amplification (IDA) - an scalable and efficient alignment strategy for superintelligence using iterative self-improvement.
The models have been optimized for coding, STEM, instruction following and general helpfulness, and have significantly higher multilingual, coding and tool calling capabilities than size equivalent counterparts.
In both standard and reasoning modes, Cogito v1-preview models outperform their size equivalent counterparts on common industry benchmarks.
Each model is trained in over 30 languages and supports a context length of 128k.
Repository: localaiLicense: llama3.1

fuseo1-deepseekr1-qwen2.5-coder-32b-preview-v0.1
FuseO1-Preview is our initial endeavor to enhance the System-II reasoning capabilities of large language models (LLMs) through innovative model fusion techniques. By employing our advanced SCE merging methodologies, we integrate multiple open-source o1-like LLMs into a unified model. Our goal is to incorporate the distinct knowledge and strengths from different reasoning LLMs into a single, unified model with strong System-II reasoning abilities, particularly in mathematics, coding, and science domains.
Repository: localaiLicense: apache-2.0
fuseo1-deepseekr1-qwen2.5-instruct-32b-preview
FuseO1-Preview is our initial endeavor to enhance the System-II reasoning capabilities of large language models (LLMs) through innovative model fusion techniques. By employing our advanced SCE merging methodologies, we integrate multiple open-source o1-like LLMs into a unified model. Our goal is to incorporate the distinct knowledge and strengths from different reasoning LLMs into a single, unified model with strong System-II reasoning abilities, particularly in mathematics, coding, and science domains.
Repository: localaiLicense: apache-2.0
Page 1